What Is Headless BI?
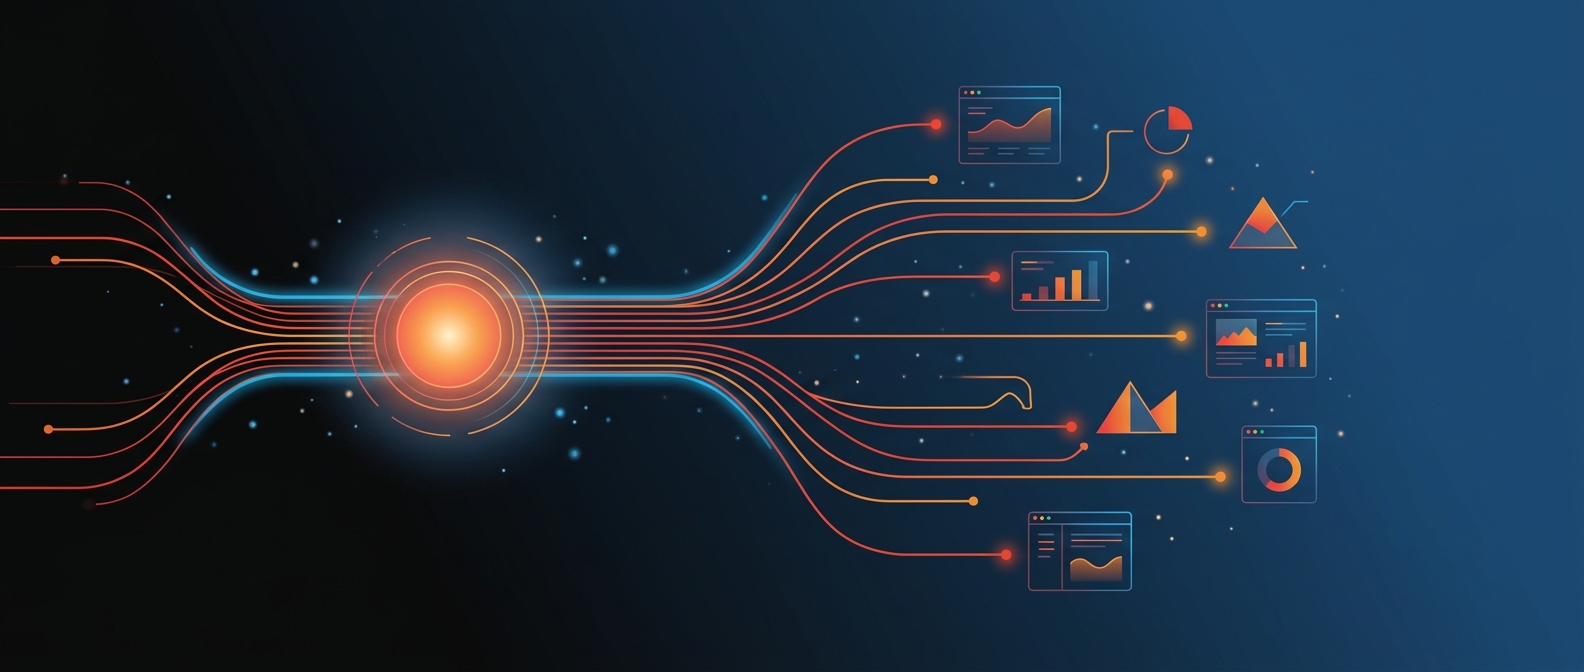
Headless BI is an approach that separates the layer where metrics and business logic are defined from the tools that display them. The "head" in traditional BI is the visualization tool, the dashboard or report a user sees. Headless BI removes the assumption that the metric definitions have to live inside that tool. Instead, the definitions live in a central, tool-independent layer, and any number of front ends, dashboards, applications, embedded charts, or AI assistants, draw from the same governed source.
The term borrows from headless software architecture, where a back end serves data to many front ends through an interface rather than being tied to one. Applied to BI, it means a metric like revenue or Days Sales Outstanding is defined once in a shared semantic layer and served consistently to everything that asks for it, rather than being redefined in each separate tool.
Why Headless BI Matters
The problem headless BI addresses is metric inconsistency across tools. In many organizations, the same metric is defined separately in Power BI, in a spreadsheet, in an embedded chart, and in whatever an AI tool calculates, and the definitions drift apart. The result is the familiar situation where two reports give two different numbers for the same thing. Headless BI keeps the definition in one place, so every tool that consumes it works from the same definition.
This matters more as the number of things consuming data grows. A modern organization doesn’t have one BI tool. It has dashboards, embedded analytics, operational applications, and now AI assistants, all needing the same metrics. Defining those metrics once and serving them to everything is far more sustainable than maintaining the logic separately in each. As AI becomes a major consumer of enterprise data, a single governed definition that the AI shares with human reporting becomes especially valuable.
How Headless BI Works
A central semantic layer. Metrics, dimensions, and business logic are defined in one tool-independent layer. This is the core of headless BI, the shared definition of what each metric means.
An interface for consumption. Front-end tools request metrics from the semantic layer through an interface or API, rather than calculating them internally. The layer returns the governed result.
Many front ends, one source. Dashboards, embedded analytics, applications, and AI tools all draw from the same layer. Each can present the data differently, but all share the same underlying definitions and governance.
In practice, Power BI semantic models work this way for many consumers: reports, Excel, XMLA-based tools and AI tools connecting through Microsoft’s native MCP all query the same semantic model. On Databricks, Unity Catalog metric views serve dashboards, SQL and Databricks Genie from one definition. Dedicated semantic-layer tools take the same approach across more front ends.
Headless BI and the Semantic Layer
Headless BI is closely tied to the semantic layer. The semantic layer is the business-ready layer that defines metrics in business terms. Headless BI is the architectural choice to make that layer independent of any single front-end tool, so it can serve many. One describes the layer, and the other describes the decision to decouple it from the visualization tool.
For an organization that has invested in a strong semantic layer, headless BI is the way to get the most from it: every dashboard, application, and AI tool consuming the same governed metrics rather than each redefining them. The value of the semantic layer compounds when it is shared this way.
Common Challenges and Best Practices
- Invest in the semantic layer first. Headless BI depends on a strong, well-defined semantic layer. The decoupling adds value only when the definitions it serves are sound.
- Govern centrally. Define each metric once, with clear ownership, so the single source stays authoritative as more tools consume it.
- Carry security through. Define row-level security once in the semantic layer rather than in each tool, then test it with a restricted user on every front end, because some roles, such as people with edit rights on a Power BI semantic model, aren’t subject to it.
- Plan for AI as a consumer. AI tools are becoming major consumers of governed metrics. Design the layer so AI and human reporting share the same definitions.
- Match front ends to need. Headless BI lets each tool present data its own way. Choose front ends for the job while keeping the shared back end.
Frequently Asked Questions
How do tools consume a headless semantic layer?
Through an interface the layer exposes. A Power BI semantic model on a Fabric capacity or Premium Per User workspace can be queried in DAX through the XMLA endpoint, opened from Excel, or reached by AI tools such as Claude through Microsoft’s native MCP. Unity Catalog metric views on Databricks are queried in SQL by dashboards, notebooks and Databricks Genie. Each front end gets the governed result instead of calculating its own.
Why is headless BI relevant to AI?
AI tools are becoming significant consumers of enterprise metrics. Headless BI lets an AI assistant draw on the same governed definitions as human dashboards, so the AI works from the same definitions as the reports instead of calculating its own.
Does headless BI replace tools like Power BI?
No. Power BI and similar tools remain the front ends users interact with. Headless BI changes where the metric definitions live, in a shared layer rather than inside one tool, so those front ends and others consume the same governed source.
Headless BI and QuickLaunch's Approach
QuickLaunch Analytics delivers one governed semantic model per system, pre-built and delivered in Power BI or Databricks, with each metric defined once from the source ERP data and validated against it. That’s the headless principle in practice: Microsoft 365 Copilot, Claude and Databricks Genie answer from the same trusted definitions as your reports, and dashboards and embedded analytics draw on the same governed measures, on a foundation refined across 250+ implementations.
About the Author